The Average Is Lying to You


A call center manager pulls up the dashboard the way she does most mornings, coffee still too hot to drink. Automation rate: up. Cost per contact: down. Service level: the best it’s been all quarter. Every number on the screen is green, and every number on the screen is telling her the year is going well.

So why does the floor feel harder to run than it did a year ago?

She can’t point to anything specific. Nobody’s quit in weeks. Escalations aren’t up, exactly. It’s just that the calls that make it to her agents lately seem to take more out of them – more silence on the line while someone reads a note, more calls that get transferred twice before they’re solved, more agents stopping by her desk to ask what they’re allowed to do about a situation the script doesn’t cover. None of that shows up as a number. The dashboard doesn’t have a field for it.

Here’s what she’s actually looking at, if she wrote it out.

Before AI, her team handled all 100 cases that came in on a given day. Some were easy – a password reset, a billing question with an obvious answer. Some were hard- an angry customer, three conflicting records, a policy that didn’t fit the situation. But on average, the work was representative of the whole. A typical case was, roughly, a real case.

Suppose AI now handles the easiest 70.

The 30 that reach her agents aren’t a smaller version of the old 100. They’re a different population. They contain more ambiguity, more conflicting information, more unhappy customers, more situations where the policy manual and the actual situation don’t line up – because AI didn’t just take the easy cases, it took the cases that were easy precisely because they didn’t require judgment. What’s left is, almost by definition, everything that does.

I’ve been thinking about this since finishing Migrating Scarcity. The book’s central claim is that technology doesn’t eliminate scarcity – it moves it. AI makes routine execution abundant, and scarcity migrates toward judgment. But there’s another consequence I didn’t spend much time on in the book. Scarcity can also move within the distribution of a single job – quietly making the average unit of remaining work harder, even as the total amount of work falls.

Which brings us back to her dashboard. Cost per contact fell because AI’s transactions are nearly free. Every blended metric that gets reported upward looks like a story about efficiency. But those averages increasingly describe the work the machine is doing, not the work her team is doing. An improving service metric doesn’t mean her agents got better at their jobs. It can mean the easy cases – the ones that used to pull the average down – aren’t reaching her agents at all anymore.

This is where it stops being a feeling she can’t name and starts being a decision someone else makes for her.

Her VP looks at the same dashboard and sees automation at 70%. The conclusion writes itself: if AI is handling seven in ten cases, the team needs roughly seven in ten fewer people. It’s a clean number, and clean numbers travel well in a budget meeting.

That conclusion might even be right, on headcount. A team handling 30 hard cases a day may genuinely need far fewer people than a team handling 100 mixed cases a day. The error isn’t necessarily the number. The error is the reasoning behind it – an assumption that capacity scales linearly with automation, while ignoring that the composition of the remaining work has changed. You can’t staff the residual 30% using the assumptions you used for the original 100%, because the residual 30% isn’t a smaller sample of the same job. It’s a harder job, done by fewer people, who now need more experience, more authority to deviate from the script, and more support than the average performer on an average day used to need.

Cut the staff by the automation rate and change nothing else, and you get a smaller team facing a harder caseload with the same training, the same authority limits, and the same thin margin for error the old team had – calibrated for a workload that no longer exists.

None of this will show up in the metrics that made the case for automation in the first place. Cost per contact will still look great. It will just be an increasingly accurate description of the transactions the machine is handling, and a decreasingly accurate one of the work left to the people still on the floor.

We keep asking what percentage of work AI will take from people. I’m starting to think that’s the wrong question.

If AI takes the easiest work first, the work left to people won’t simply be less of the old work. It will be different work.

And that means the average we’ve been managing may no longer describe the people we’re managing.
Why Everyone Is Busy and Everything Is Late


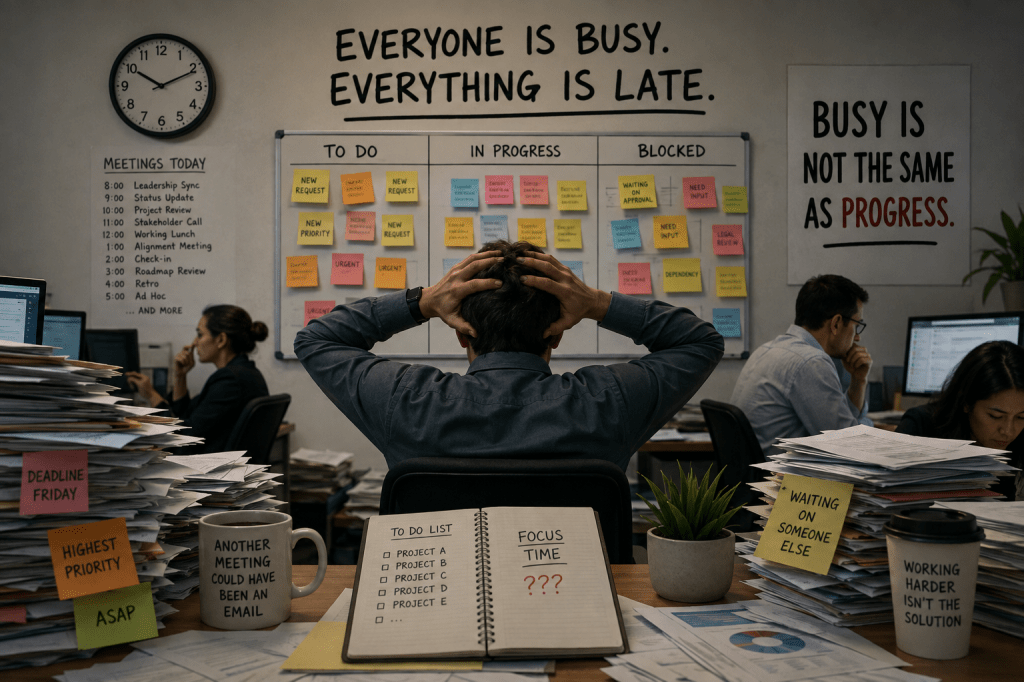
Every team lead has lived some version of this. People are working long hours. Calendars are wall-to-wall meetings. Everyone seems busy. Yet deadlines keep slipping, leadership is unhappy with the output, managers insist they don’t have enough talent, and the people doing the work are quietly burning out.

The instinctive response is predictable: hire more people, push harder on deadlines, replace the supposed underperformers.

Sometimes there really is a talent problem, and no amount of process fixing will substitute for it. But often something else is happening. The organization has confused how busy people are with how much work is actually getting finished. A team can be operating at full capacity while the work itself is barely moving.

Busy Is Easy to See

Organizations are remarkably good at measuring activity. We see full calendars, count how many projects someone owns, track utilization, hours, tickets, deliverables. When everyone is stretched, it feels like the organization must be extracting maximum productivity from its people.

But activity isn’t flow. Flow is the rate at which work actually moves from start to finish, as opposed to how occupied people look while it’s in motion.

Take a team of ten working on three important projects, and hand them twelve instead. Everyone immediately gets busier: more meetings, more status updates, more dependencies, more deadlines. Nobody looks underutilized. But each project now spends more time waiting for someone’s attention. People switch constantly between tasks. Decisions queue up. Work gets started faster than it gets finished.

Individual utilization can rise even as organizational throughput falls. That’s the paradox: everyone can be individually busy while the organization is collectively slow.

Measure the Work, Not Just the People

When a team keeps missing deadlines, three questions matter more than any hours dashboard.

How much work is in progress? How many “important” projects is each person carrying? How much new work enters the system each month versus how much actually gets completed? A team that starts ten things and finishes six hasn’t created capacity. It’s created four more unfinished projects competing for attention.

How quickly does work actually move? Look past hours worked. How much of the week is focused work versus meetings, status updates, and coordination? Pull real calendar data. Check how many recurring meetings actually produce a decision. The goal isn’t to kill collaboration. It’s to understand why a team logging fifty hours can produce surprisingly few hours of real concentration.

How much time does work spend waiting? This is the least visible constraint of all. How many approvals does routine work require? How often is someone blocked waiting on another team or manager to decide? A task can take ten hours of actual effort and three weeks waiting for permission to proceed. From outside, the team looks slow. The real constraint is decision latency, not effort.

Work in progress, flow, and waiting time tell you far more than a busy calendar ever will.

There’s a fourth thing worth checking, not a question this time but a design choice organizations make without noticing: how much spare capacity the system is allowed to carry.

Why 100% Utilization Backfires

Most managers instinctively dislike unused capacity. If someone has room in their schedule, surely there’s another project for them. So organizations keep filling the space.

But systems running near maximum capacity become extremely sensitive to variability. One unexpected fire, whether it’s a customer escalation, a resignation, or a technical failure, pushes everything else behind because there’s no shock absorber left.

Visible slack isn’t waste. It’s often what lets a system keep moving when reality deviates from the plan.

But slack is politically hard to defend because busyness is visible and resilience isn’t. A packed calendar looks productive. Someone with room to think looks underutilized.

So we optimize for what we can see, and eventually everyone is busy.

How System Problems Get Mistaken for Talent Problems

This is where diagnosis usually goes wrong. A team misses deadlines, so leadership concludes it needs stronger people.

Sometimes that’s right. But before accepting it, ask one question:

If the team’s total workload were cut by a third, would the talent gap still be obvious?

If yes, there’s probably a real skills problem. That’s the signal worth hiring against: a specific capability the team genuinely lacks, still visible once the noise of overload is removed.

If no, capable people may simply have been operating inside a badly overloaded system. Someone juggling six priorities can’t go deep on any of them. A manager spending thirty hours a week in meetings has little time left to actually manage.

Under those conditions, system failure looks a lot like individual underperformance. And adding more people doesn’t necessarily help. More people can simply mean more coordination, more meetings, and more dependencies unless the operating model itself changes.

What Leaders Can Actually Change

Reduce work in progress. Give teams a real top three, not a top ten disguised as one. When something new becomes urgent, force an explicit decision about what drops.

Protect flow. Remove recurring meetings that don’t produce decisions or move work forward. Protect uninterrupted time, and don’t consume synchronous capacity when asynchronous communication will do.

Attack waiting time. Push routine decisions closer to the people doing the work. Approval should scale with risk, not hierarchy.

Stop planning at theoretical maximum capacity. Leave room for the unexpected. It isn’t an exception. It’s part of operating reality.

Change what gets celebrated. If the person emailing at midnight gets more recognition than the one who reliably delivers during normal hours, the culture has already told everyone what it actually values. Leaders can’t preach sustainable performance while rewarding visible exhaustion.

The Real Productivity Problem

Burnout, missed deadlines, and complaints about talent often look like three separate problems. They’re usually three symptoms of the same operating system: too much work enters, too little exits, and everything in between competes for the same finite attention.

The overloaded organization’s instinct is to demand more effort. But when everyone is already busy, effort was never the missing ingredient.

The job isn’t to maximize how busy people look. It’s to maximize how reliably important work gets finished.

Sometimes the fastest organization is the one willing to leave some capacity unused.

The Verification Era: What Happens When Code Becomes Abundant


The prevailing narrative in tech assumes AI is making software engineers dramatically more productive. That may hold true if you only measure code generation, but it falls apart when you look at software delivery. We are confusing the speed of typing code with actual system velocity.

For commodity, CRUD-heavy work where “good enough” truly suffices, AI genuinely collapses the friction of basic implementation. But in high-stakes domains—where failure affects security, financial integrity, or systemic stability—writing code was never the primary constraint. Technology rarely eliminates structural constraints; it simply migrates them. Make one layer of a system cheap and abundant, and scarcity shifts elsewhere. Today, the marginal cost of generating implementation code is collapsing, making it vastly cheaper to produce than to understand, integrate, and validate.

The bottleneck hasn’t been solved. It has just moved downstream.

The Migration of Scarcity

In the pre-AI era, the primary friction in software development was translation: converting business domain requirements into syntactically correct, performant code. Today, LLMs can generate large blocks of implementation in seconds. But shipping software was never just about raw typing speed. It is about integration, state management, security boundaries, and operational coherence.

When generation capacity increases dramatically, existing review and testing processes that worked fine at lower volumes inevitably come under pressure. Pull request queues fill up, integration testing becomes noisier, and regression surfaces expand dramatically. More generated code creates vastly more state space to test, secure, and operate.

This isn’t an anti-AI argument; it is a systems argument. Calling review queues “just a process problem” misses the fundamental scale shift. When generation velocity outpaces an organization’s capacity to verify and safely deploy what was produced, you haven’t accelerated delivery. You’ve simply created a high-speed traffic jam downstream.

Slop Debt and the Comprehension Gap

We all know what classic technical debt looks like: messy abstractions, missing tests, and hardcoded logic written under deadline pressure. It’s ugly, but it is visible, accumulated over time through conscious trade-offs, and familiar to refactor.

The AI era introduces a far more deceptive challenge: Slop Debt. Slop debt isn’t simply bad or unreadable code; it is code generated instantly at scale whose production cost has collapsed while its comprehension and verification costs have not.

AI-generated code often looks immaculate. It passes linting, features clean syntax, and arrives with unit tests attached. But slop debt is dangerous precisely because it is invisible—it satisfies basic automated checks while embedding subtle semantic errors or invariant violations that only emerge under operational pressure.

Even when the output is well-structured, generation scales dramatically faster than human comprehension. An agent can produce thousands of lines of implementation in minutes, but an organization still requires human judgment, domain context, and operational experience to verify that those lines correctly represent business invariants.

One of the most dangerous codebases in 2026 may be the pristine, AI-generated system that no human on the team actually understands well enough to debug when it fails in production. When generation is cheap, comprehension becomes the scarce asset.

Judgment as the Competitive Moat

Recognizing this shift is not about protecting titles or gatekeeping junior developers; it is a question of cognitive capacity and epistemology. AI separates implementation fluency from architectural judgment.

For years, early-career engineers built leverage through syntax mastery and framework fluency. AI rapidly commoditizes that layer. But a senior engineer’s value was never how fast they could write a loop; it was their cynical, battle-tested intuition for race conditions, edge cases, and failure domains. An engineer who has not yet internalized these failure modes cannot recognize them in an agent’s output, regardless of prompt quality.

If junior engineers rely on AI before mastering core fundamentals, they risk becoming human rubber stamps for a probabilistic model—unable to audit what they do not understand. Conversely, senior judgment becomes dramatically more valuable when paired with abundant generation. Experienced engineers can immediately evaluate whether a generated block strengthens the system or introduces subtle, systemic fragility.

The competitive moat is no longer typing speed or syntax recall. It is the judgment required to know whether a model’s output should exist in production at all.

From Drivers to Governors

If your mental model of AI is still pasting prompts into a chat window and copying code back into an IDE, you are looking at an outdated workflow. The unit of AI-assisted engineering has moved from the isolated prompt to the end-to-end workflow.

Modern coding agents don’t just autocomplete functions. They inspect repository trees, modify multi-file architectures, execute test suites, catch runtime errors, and submit structured pull requests. As these agents operate asynchronously, the engineer’s role shifts from driver to orchestrator. You are no longer primarily producing raw code; you are governing a production system—establishing the boundary conditions, safety policies, and control surfaces under which autonomous agents run.

Embedding probabilistic models and agentic loops into backend architectures introduces semantic non-determinism—not the familiar timing jitter of distributed networks, but uncertainty at the level of meaning and execution logic. Traditional systems handle latency; probabilistic agents can change what a system does, not just when it does it.

Verification can no longer mean checking whether code compiles or passes a unit test. It requires building deterministic guardrails around probabilistic engines to handle variable latency, schema drift, tool-selection errors, and cascading failure states.

The Recursive Scarcity Chain

When human verification becomes the bottleneck in an era of abundant code, the verification function itself must be industrialized and automated. The future lies in building AI-driven verification systems—agents that generate formal specifications, run adversarial simulations, execute invariant checks, and enforce dynamic guardrails.

Automating verification doesn’t create an infinite regress. It simply moves the constraint to a higher level. The question becomes: Who verifies the verifier?

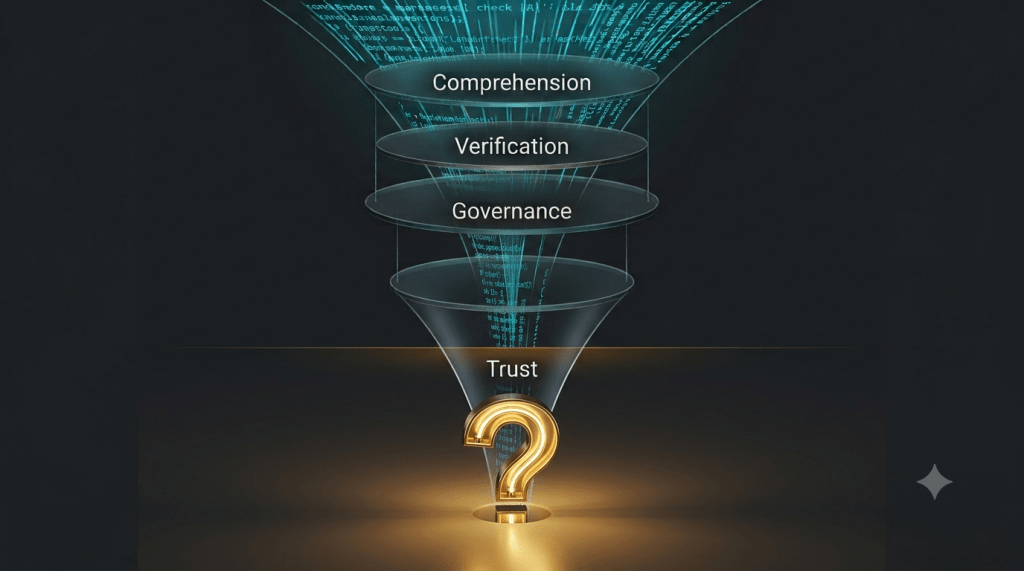
The evolution of the engineering stack is not a linear waterfall pipeline, but a recursive shift in binding constraints. As technology automates or commoditizes one layer, value and friction migrate downstream. Looking at this migration shows where economic leverage is concentrating today:

Generation. Writing implementation code drops from a manual bottleneck to a collapsing marginal cost.

Comprehension. As syntax and framework boilerplate get absorbed by agents, value shifts to system comprehension and deep domain context.

Verification. As routine validation gets automated, test adequacy, invariant design, and knowing what must be verified become the new scarcity.

Governance. Automated verification systems handle routine checks, elevating architecture, boundary setting, and policy enforcement into the primary control surfaces.

Trust. As agentic workflows manage generation and verification, economic value increasingly centers on establishing system-level trust.

When implementation becomes cheap, the premium shifts increasingly toward comprehension, verification, architectural judgment, and system accountability. The defining question of this era is no longer “How fast can we build this?” but “What happens when it fails—and can we prove it is safe to trust?”

The most valuable engineers of the AI era won’t be the ones who generate the most code. They will be the ones who build the architectures and control systems that determine when AI should be trusted, when it should be constrained, and when it should be rejected.